Why Gambo AI Shut Down in 2026: What Really Happened to the Game Vibe Coding Agent
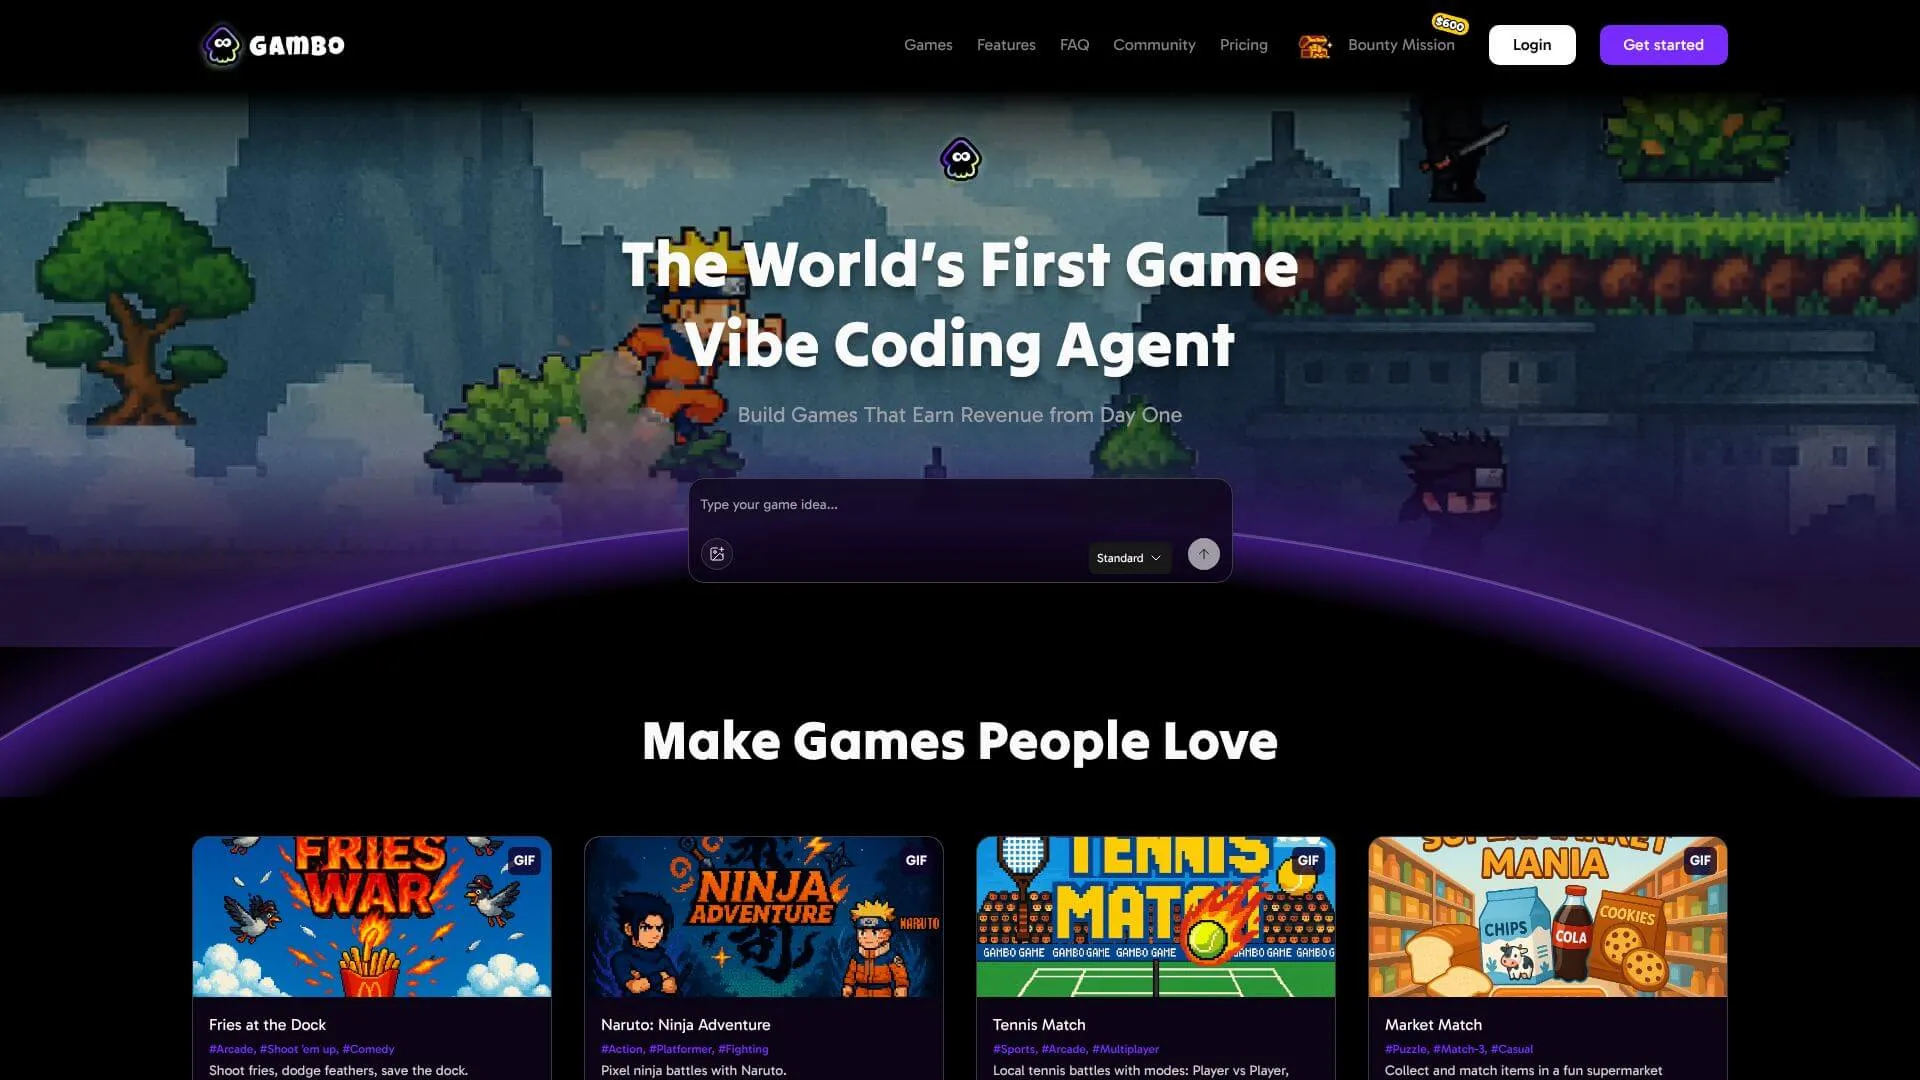
Why did Gambo AI shut down in 2026? A fact-checked look at its closure, financial pressure, product economics, and unfinished business model.
Latest reviews, launch notes, workflow guides, and insights across the AI IDE ecosystem.
AI Coding AgentsAI VideoConsumer AIFastVLMGPT-OSSLocal AIOpen-Weight ModelsTRAETraeIDE ArchiveTraeIDE Guides
Claude Code
Codex
Developer WorkflowsAI BuildersBrowser AgentsAgent InfrastructureAnthropicCognitionCursorLovableOpen SourceOpenAIReplit
Why did Gambo AI shut down in 2026? A fact-checked look at its closure, financial pressure, product economics, and unfinished business model.

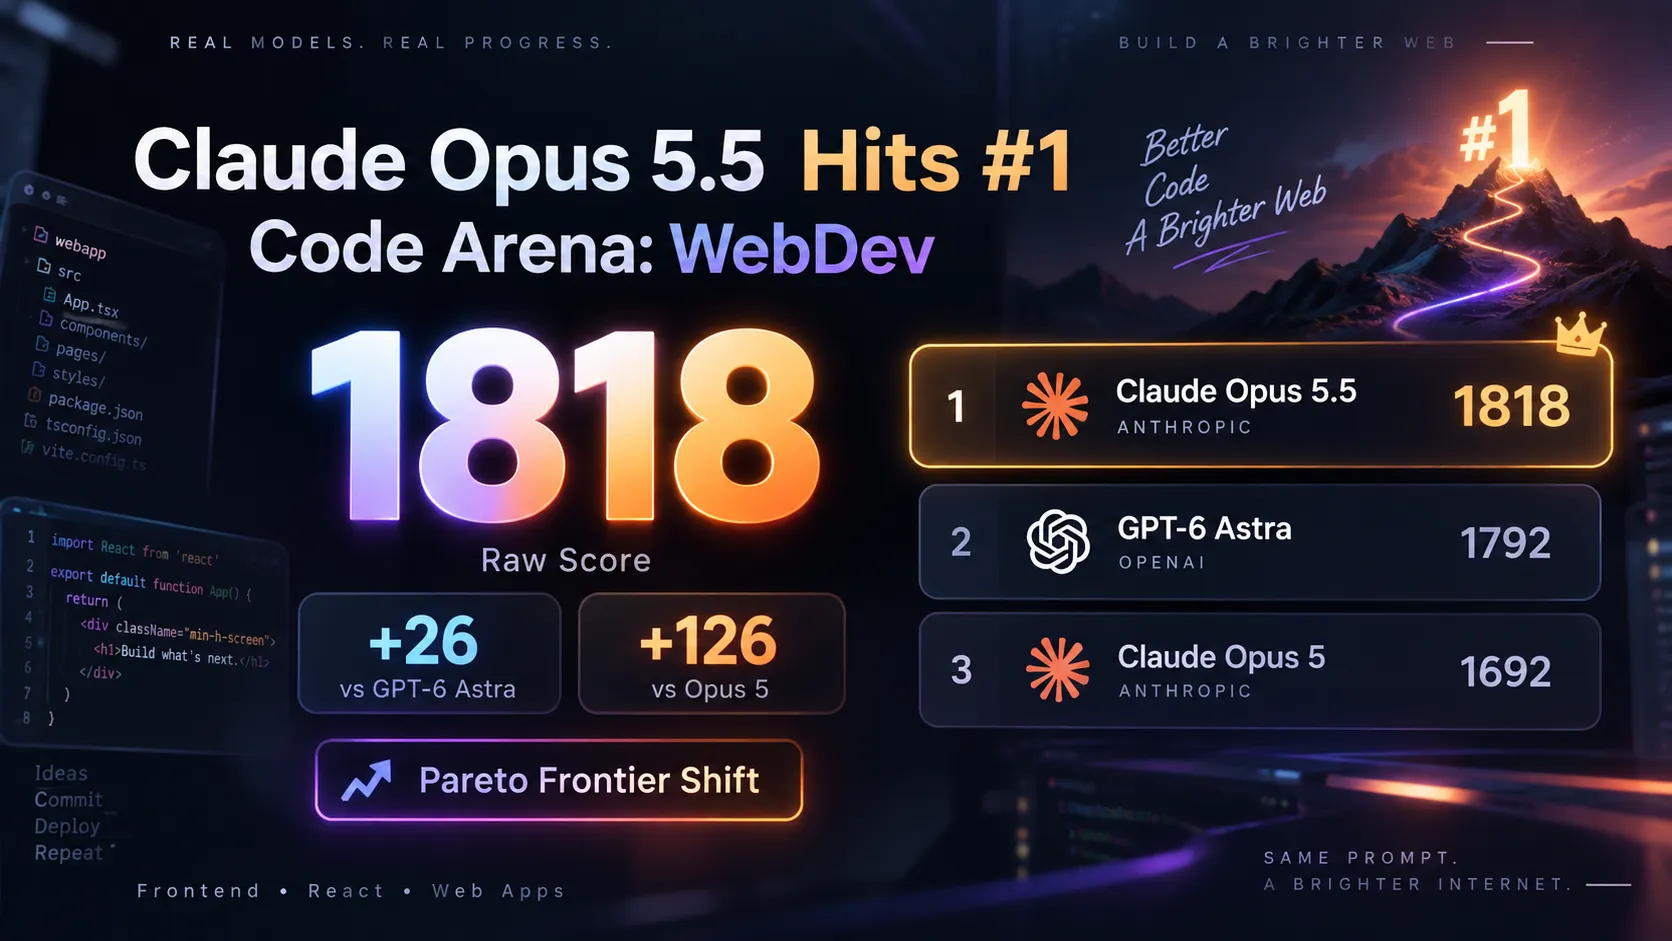
Claude Opus 5.5 hits 1818 in Code Arena WebDev, leading GPT-6 Astra by 26 points. See what the score, pricing, and uncertainty mean.

OpenCodex is an open-source local proxy that lets Codex and Claude Code use Claude, Gemini, Grok, DeepSeek, Ollama, and more.

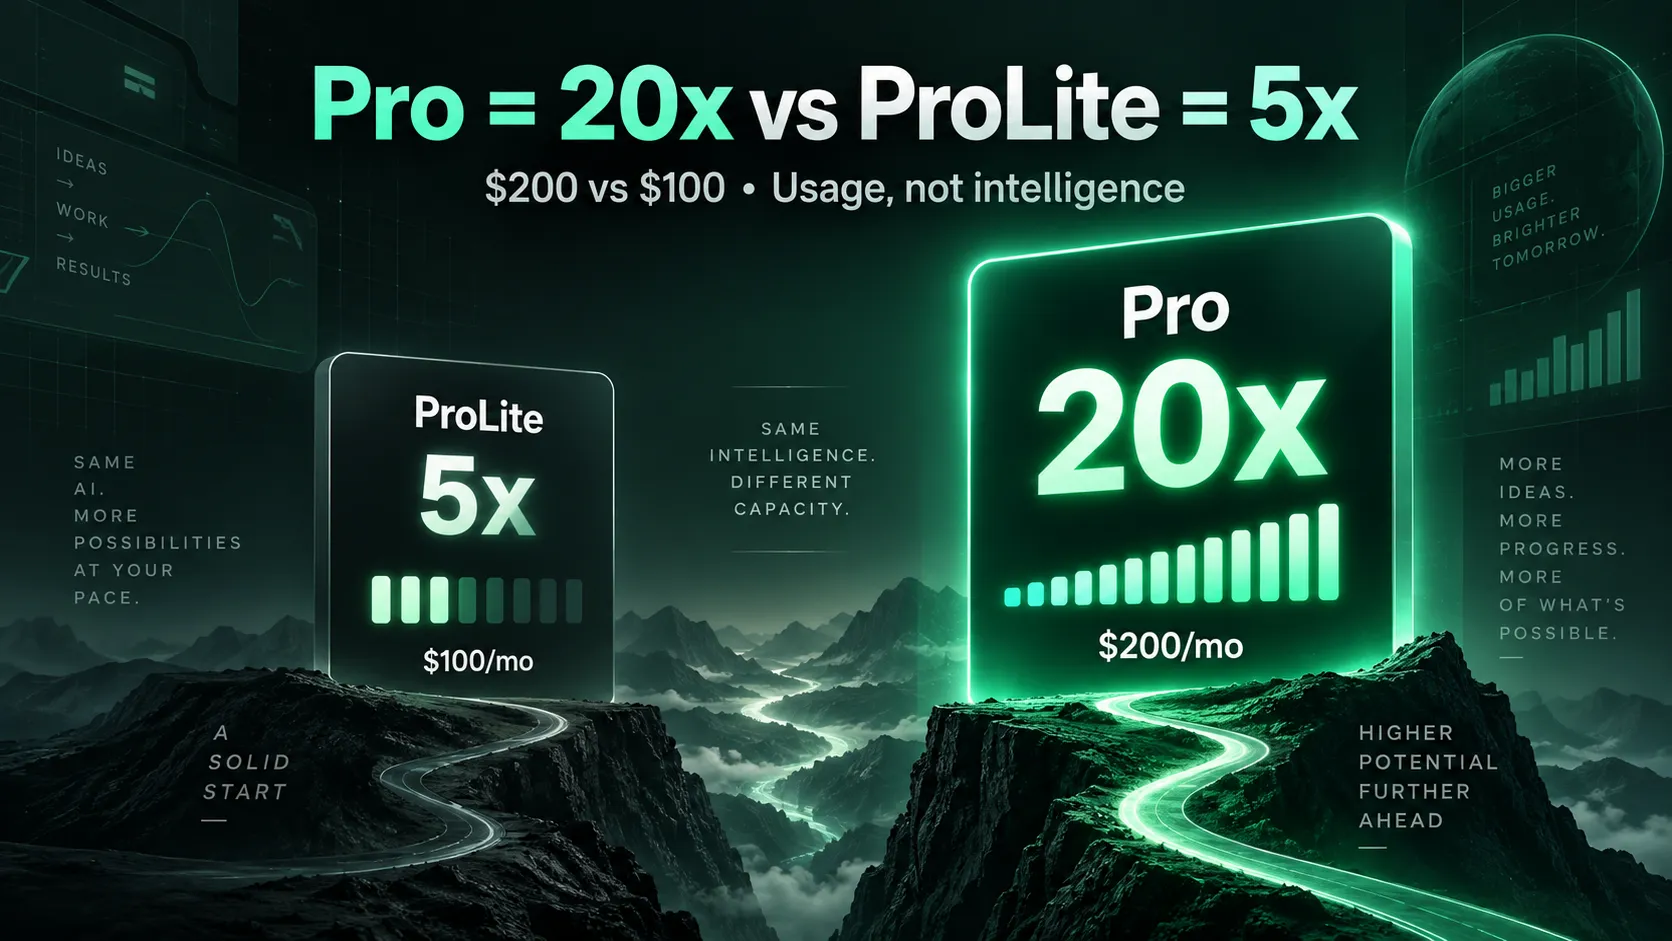
ChatGPT Pro 20x vs Pro 5x compared: pricing, Codex limits, value per dollar, who needs each tier, and the September 2026 20x signup pause.

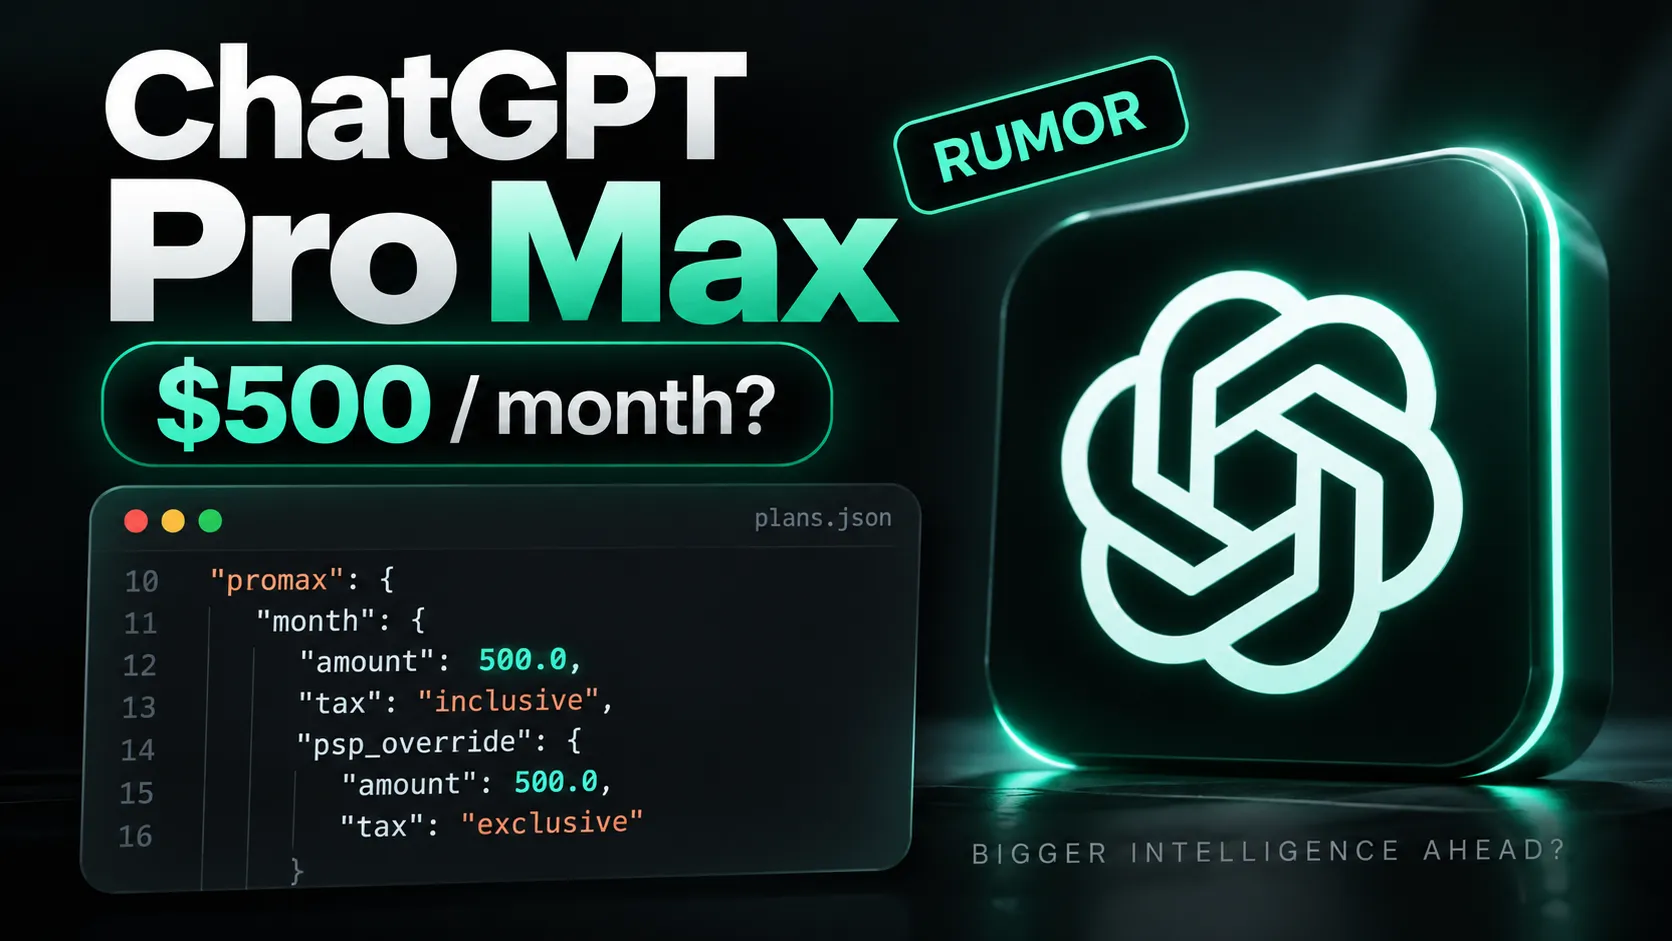
ChatGPT Pro Max may become OpenAI's most expensive consumer plan. Here's what the leaks show, what $500 could buy, and what remains unconfirmed.

Tencent will shut down QClaw on December 24, 2026. See the timeline, refunds, WorkBuddy migration, data deadlines, and what the move means.

Claude Opus 5.5 vs GPT-6 Astra vs Grok 4.7: compare coding, agents, benchmarks, context windows, speed, and 2026 API pricing.

Learn how Microsoft connects traditional applications with AI agents through A2A, helping enterprises improve collaboration efficiency and move towards intelligent operations.

DiffuCoder-7B-Instruct is Apple’s instruction-tuned diffusion language model for code. Its official model card documents the Apple AMLR license, model files and custom inference architecture.

CLaRa is an Apple research model that bridges retrieval and generation with continuous latent reasoning. The official Hugging Face model card provides the license, files and usage entry points.

Compare S0, S2 and the larger variants, then run image–text matching with your own labels. MobileCLIP2 produces embeddings for classification and retrieval; use FastVLM when you need a written answer.

Which small vision-language model runs on your phone, Mac or in the browser? Compare FastVLM, SmolVLM2, LFM2.5-VL, Gemma 4, Gemma 3n, Qwen3-VL, Moondream, MiniCPM-V and PaliGemma 2 by size, video, browser and MLX support and license.

How to use Apple’s Foundation Models framework: LanguageModelSession, guided generation, tool calling, multimodal image prompts, Dynamic Profiles, the LanguageModel protocol, Python SDK and fm CLI. Includes Swift examples and the WWDC26 session list.

Apple’s third-generation foundation models (June 2026): AFM 3 Core (3B on-device), AFM 3 Core Advanced (20B sparse, multimodal), AFM 3 Cloud, ADM 3 Cloud and AFM 3 Cloud Pro. What each does and how the Foundation Models framework exposes them.

The STARFlow family scales autoregressive normalizing flows to high-resolution images (STARFlow), video (STARFlow-V, 2026) and unified multimodal understanding plus generation (STARFlow2, August 2026). Architecture, papers and code links.

Luce (Apple, August 2026) turns a single object image into relightable PBR Gaussians with albedo, metallic-roughness and normals, plus an optional textured mesh. What it outputs, how it compares to SHARP, and where to follow the release.

AIMv2 is Apple’s family of open vision encoders (0.3B–2.7B) pre-trained with a multimodal autoregressive objective. Checkpoints for 224/336/448 px and native resolution, with PyTorch, JAX and MLX backends.

Apple Depth Pro estimates metric depth and focal length from a single image in about 0.3 s on a GPU. Try it in your browser, then run it with the official CLI, Transformers or ONNX.

A curated hub of Apple’s open machine-learning models: FastVLM, Depth Pro, MobileCLIP2, AIMv2, SHARP, Luce, STARFlow and the Apple Foundation Models. Browser demos, local run guides and comparisons.

Measure model load time, time to first token and tokens per second for FastVLM-0.5B on your own GPU with WebGPU, then share the result. Runs entirely in your browser.