On This Page8 sections
Key Takeaways
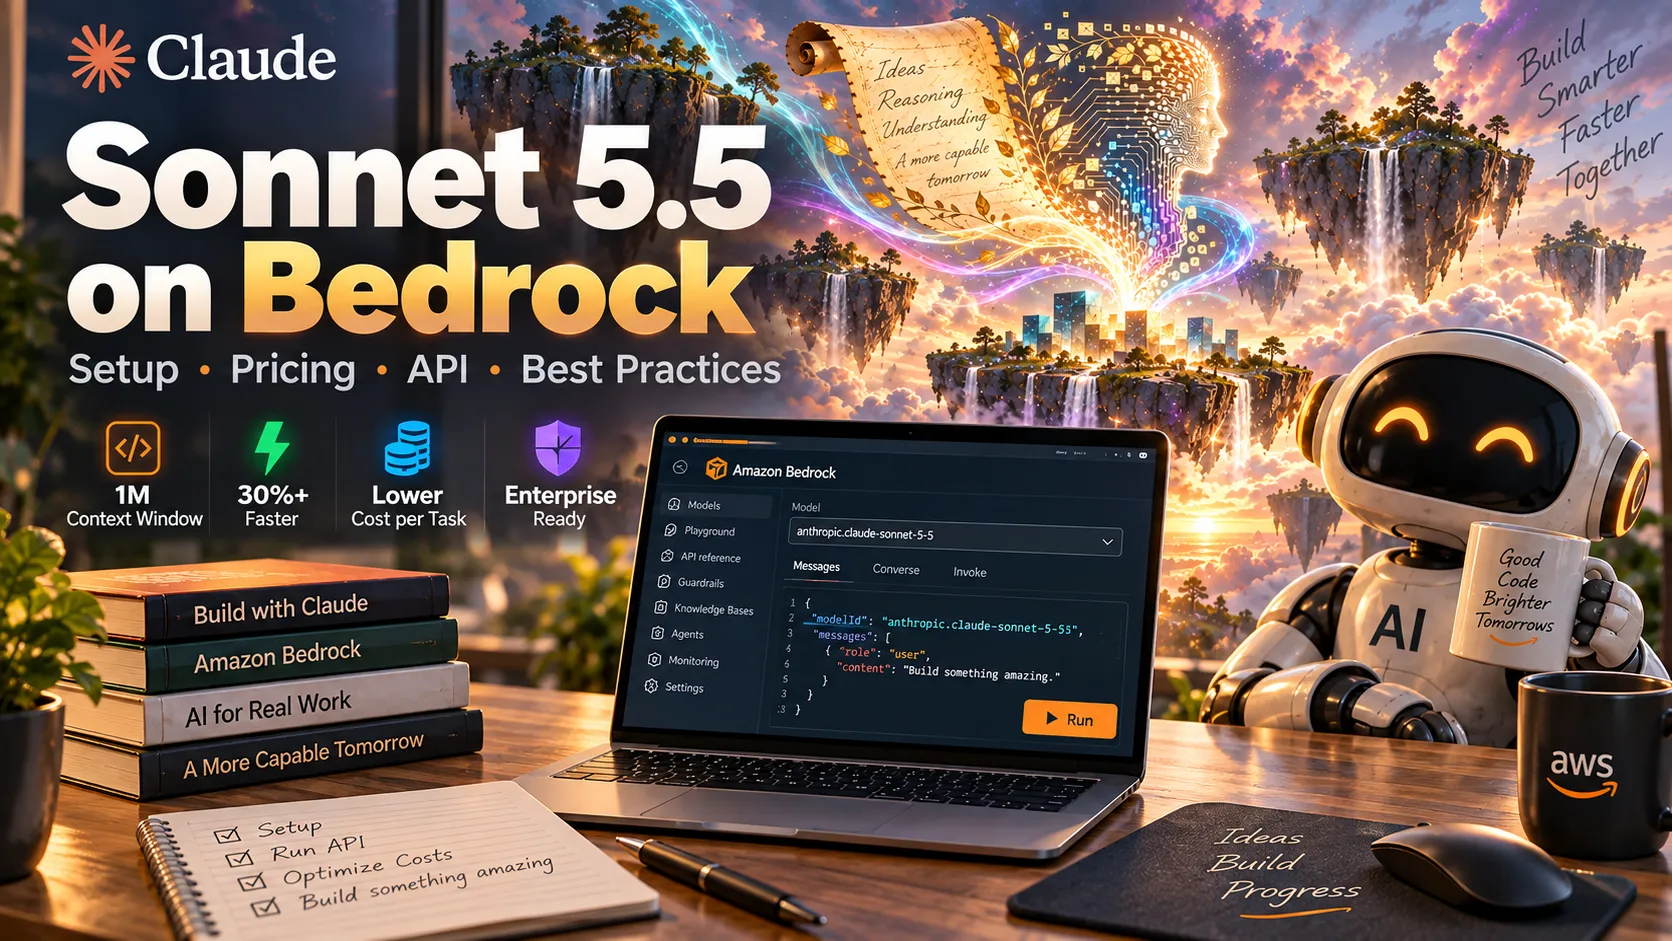
- Claude Sonnet 5.5 launched on Amazon Bedrock on September 28, 2026. AWS positions it as a faster, more efficient Sonnet for well-scoped coding and knowledge-work tasks.
- The Bedrock model supports a 1 million-token context window and up to 128K output tokens, with text and image input, text output, and adaptive reasoning. Its documented knowledge cutoff is June 2026.
- For
bedrock-runtime, a key on-demand identifier isglobal.anthropic.claude-sonnet-5-5. AWS also currently documents US and EU geographic inference profiles. - Sonnet 5.5 supports the Messages, Converse, and Invoke APIs on
bedrock-runtime; AWS currently lists Chat Completions and Responses as unsupported. - Anthropic lists Sonnet 5.5 at $2 per million input tokens and $10 per million output tokens, while reporting 30%+ faster generation and up to 30% lower cost per task than Sonnet 5.
- The most important production metric is therefore cost per completed task, not simply cost per million tokens.
Claude Sonnet 5.5 on Amazon Bedrock is more than another model ID. It changes the practical model-selection equation for teams building coding agents, enterprise assistants, RAG systems, document workflows, and high-volume knowledge applications inside AWS.
The most useful question is no longer whether Sonnet can approach top-tier model quality. It is which workloads still justify Opus 5.5, and which can move to Sonnet 5.5 without sacrificing task success.
What Is Claude Sonnet 5.5 on Amazon Bedrock?
Claude Sonnet 5.5 is Anthropic's September 2026 Sonnet release, offered through Amazon Bedrock as a managed foundation model. AWS describes it as a smarter and more efficient upgrade over Sonnet 5, particularly for focused software-development and knowledge-work workloads.
Bedrock is significant because organizations can combine the model with AWS-native infrastructure and governance capabilities such as:
- AWS IAM for access control
- AWS CloudTrail for auditing
- Amazon CloudWatch for monitoring
- Amazon Bedrock Guardrails
- Knowledge Bases for Amazon Bedrock
- Bedrock Agents
- Prompt caching
- Cross-Region inference profiles
AWS currently marks Sonnet 5.5 as active, with an EOL no sooner than September 28, 2027 and a six-month legacy period. That lifecycle information matters for teams planning multi-quarter production deployments rather than short-lived prototypes.
Sonnet 5.5 Bedrock Specs at a Glance
| Capability | Claude Sonnet 5.5 on Bedrock |
|---|---|
| Launch date | September 28, 2026 |
| Context window | 1M tokens |
| Maximum output | 128K tokens |
| Knowledge cutoff | June 2026 |
| Input | Text, images |
| Output | Text |
| Reasoning | Adaptive thinking supported |
| Effort levels | Low, Medium, High, Xhigh, Max |
| Bedrock runtime APIs | Messages, Converse, Invoke |
| Streaming | Supported |
| Prompt caching | Implicit and explicit caching supported |
| Bedrock Guardrails | Supported on bedrock-runtime |
| Knowledge Bases | Supported on bedrock-runtime |
| Bedrock Agents | Supported on bedrock-runtime |
| Computer use | Supported |
| Structured outputs | Not currently listed as supported on bedrock-runtime |
AWS's model documentation states that adaptive thinking is supported and exposes multiple effort levels.
This is operationally important because reasoning effort becomes another cost-and-latency control. A deterministic extraction task should not automatically receive the same reasoning budget as a difficult repository-wide debugging problem.
Why Sonnet 5.5 Matters More Than Its Token Price Suggests
The headline token price does not fully explain the upgrade.
Anthropic lists Sonnet 5.5 at $2 per million input tokens and $10 per million output tokens. Cache reads are listed at $0.20 per million tokens and cache writes at $2.50 per million. Yet Anthropic reports that Sonnet 5.5 generates output 30%+ faster than Sonnet 5 and can cost up to 30% less per task.
The distinction is per-token cost versus task efficiency.
An agent that resolves a bug in six tool loops instead of ten can be substantially cheaper even if every token costs the same. Better task completion can reduce:
- Output-token consumption
- Agent reasoning steps
- Tool-call count
- Failed attempts
- Corrective prompts
- Human review time
- Queue occupancy
- Downstream compute usage
This is why production teams should measure dollars per accepted result, tokens per successful task, and latency to verified completion rather than comparing models only by their published token rates.
Sonnet 5.5 Benchmarks: What the Numbers Actually Mean
Anthropic reports a large coding improvement between Sonnet 5 and Sonnet 5.5. Published results include: Anthropic
| Benchmark | Sonnet 5.5 | Sonnet 5 | Opus 5.5 |
|---|---|---|---|
| Terminal-Bench 4.0 | 70.6% | 10.3% | 66.4% |
| FrontierCode 1.1 Main | 46.2% at Max | 42.4% | 54.4% |
| CursorBench 4.0 | 55.5% | 34.1% | 57.8% |
| GDPval-AA v2.1 | 1844 | 1449 | 1846 |
| AA-Briefcase v1.1 | 1811 | 1359 | 1822 |
These numbers should not be read as universal rankings. Benchmark harnesses, reasoning-effort settings, tools, time limits, and agent implementations can materially affect scores.
Anthropic also notes that some third-party evaluations used a pre-release Sonnet 5.5 deployment affected by a structured-output bug that was subsequently fixed.
The broader pattern is more useful than any single score: Sonnet 5.5 closes much of the gap with Opus 5.5 on bounded tasks, while Opus remains better suited to complex work where the model must decide what the task really requires.
Sonnet 5.5 vs Opus 5.5 on Bedrock
AWS provides a useful distinction between these models.
Choose Sonnet 5.5 when the approach is already clear and execution is the main challenge. AWS highlights feature implementation, bug fixing, requirements verification, SQL generation, UI/UX testing, alert handling, document editing, spreadsheet work, and similar repeatable tasks.
Choose Opus 5.5 when the task itself requires substantial judgment. AWS cites release debugging, multi-PR feature stacks, major security reviews, complex migrations, financial research, contract redlining, and long analyses as stronger Opus-style workloads.
A practical production hierarchy is therefore:
- Sonnet 5.5: default execution model
- Opus 5.5: escalation model for ambiguity, risk, or repeated failures
- Rules or cheaper models: deterministic preprocessing, classification, extraction, and routing
This architecture is usually more economical than routing every request to the most expensive model.
Sonnet 5.5 Bedrock Model IDs
Model identifiers are one of the easiest places to introduce deployment errors.
AWS currently documents the base model ID as:
anthropic.claude-sonnet-5-5
For Global cross-Region inference through bedrock-runtime, use:
global.anthropic.claude-sonnet-5-5
AWS also currently lists geographic inference IDs including:
us.anthropic.claude-sonnet-5-5eu.anthropic.claude-sonnet-5-5
The exact options depend on the source Region. Current AWS documentation shows Global support from many commercial Regions, while geographic support for Sonnet 5.5 is not universal. For example, the current model card shows Global but not Geo support for several APAC source Regions, including Taipei, Tokyo, Seoul, Singapore, and Sydney.
That creates an important compliance rule: do not infer data residency simply from the Region in which the API client is running.
How to Call Sonnet 5.5 on Bedrock with Boto3
AWS's launch guidance demonstrates bedrock-runtime with the Global cross-Region inference profile. A minimal implementation looks like this:
import boto3
import json

client = boto3.client(
    "bedrock-runtime",
    region_name="us-east-1",
)

response = client.invoke_model(
    modelId="global.anthropic.claude-sonnet-5-5",
    contentType="application/json",
    accept="application/json",
    body=json.dumps({
        "anthropic_version": "bedrock-2023-05-31",
        "max_tokens": 4096,
        "messages": [
            {
                "role": "user",
                "content": "Review this function for correctness and return the fixed code."
            }
        ]
    }),
)

result = json.loads(response["body"].read())

text = next(
    block["text"]
    for block in result["content"]
    if block["type"] == "text"
)

print(text)
AWS's own example handles an important Sonnet 5.5 behavior: a response can contain a thinking block before the text block. Applications should locate the desired block by type rather than blindly reading result["content"][0].
That small change can prevent brittle migrations from older Claude integrations.
Invoke, Converse, or Messages: Which API Should You Use?
Sonnet 5.5 currently supports Invoke, Converse, and Messages through bedrock-runtime. AWS lists Chat Completions and Responses as unsupported.
A useful selection rule is:
- Use Converse for Bedrock-native applications that may swap among compatible foundation models.
- Use InvokeModel when lower-level request control is useful.
- Use Messages when preserving Anthropic-native messaging semantics matters.
- Do not architect a new Bedrock integration around OpenAI-style Responses or Chat Completions assumptions for Sonnet 5.5, because AWS does not currently list those interfaces as supported.
AWS's model card recommends bedrock-runtime for new applications whenever possible.
bedrock-runtime vs bedrock-mantle
AWS documents two endpoint families for Sonnet 5.5, and they should not be treated as equivalent.
bedrock-runtime is the richer Bedrock-native path. The current model card lists integrations such as Guardrails, Knowledge Bases, Agents, model evaluation, prompt management, flows, prompt optimization, caching, streaming, and computer use.
bedrock-mantle exposes an Anthropic Messages-compatible endpoint and can be relevant when a deployment needs a more Anthropic-native interface or supported In-Region behavior. However, many Bedrock-native capabilities are not listed as available through Mantle.
The architectural decision is therefore straightforward:
- Prefer
bedrock-runtimefor deeply integrated AWS applications. - Evaluate
bedrock-mantlewhen endpoint compatibility or supported single-Region behavior is the overriding requirement. - Never assume a feature available on one endpoint automatically exists on the other.
Cross-Region Inference and Data Residency
Cross-Region inference is both a performance feature and a compliance decision.
AWS distinguishes three routing concepts:
- In-Region: processing stays within one Region.
- Geo cross-Region: Bedrock can route requests within a defined geography such as the US or EU.
- Global cross-Region: Bedrock may route requests to supported commercial Regions globally.
For Sonnet 5.5, Global CRIS is the broadest bedrock-runtime option, while current documentation also lists US and EU Geo profiles for supported source Regions.
A common mistake is treating the global. prefix as merely a performance alias. It is not. Global routing has data-residency implications.
Before deploying sensitive workloads:
- Identify whether prompts can contain regulated or residency-sensitive information.
- Check the actual inference profile available from every source Region.
- Validate IAM policies and AWS Organizations SCPs against all required destination Regions.
- Do not assume an allowed source Region means every possible destination Region is allowed.
- Re-check Global routing configuration as AWS expands infrastructure.
AWS notes that the destination set of a Global inference profile can change over time, while geographically scoped profiles provide tighter geographic boundaries.
Prompt Caching Is One of the Biggest Cost Levers
Claude Sonnet 5.5 supports implicit and explicit prompt caching on Bedrock.
AWS currently documents the following explicit-cache limits:
- 512-token minimum per cache checkpoint
- Up to 4 cache checkpoints per request
- 5-minute and 1-hour TTLs
- Cache checkpoints supported in
system,messages, andtoolsAWS 文档
Caching is especially useful for:
- Large system prompts
- Long agent tool definitions
- Repository conventions
- Repeated policy documents
- Stable RAG context
- Product catalogs
- Schemas
- Multi-turn coding sessions
The practical optimization rule is to put stable reusable content before frequently changing request-specific content.
A 30,000-token agent prefix can become dramatically cheaper across repeated calls if most of that prefix is cacheable. Conversely, a poorly structured prompt that changes near the beginning can reduce the usefulness of caching.
The 1M Context Window Is Powerful, but It Is Not Free Storage
A one-million-token context window makes Sonnet 5.5 suitable for large repositories, long document collections, extended conversations, and complex multimodal inputs.
However, sending more context is not automatically better.
Very large prompts can increase:
- Input cost
- Time to first token
- Retrieval noise
- Prompt-injection exposure
- Irrelevant evidence
- Evaluation difficulty
For most RAG and code-assistant applications, a better strategy remains:
- Retrieve a high-recall candidate set.
- Rerank candidates for task relevance.
- Include only strong evidence with clear provenance.
- Cache stable context.
- Expand toward the full context window only when the task genuinely requires it.
The 1M window should be treated as available capacity, not a target prompt size.
Best Sonnet 5.5 Bedrock Use Cases
Sonnet 5.5 becomes especially attractive when work is frequent, bounded, and easy to verify.
Coding agents
- Implementing a defined issue
- Fixing a reproducible bug
- Refactoring toward a specified target
- Writing tests
- Reviewing a bounded diff
- Verifying code against acceptance criteria
Operational assistants
- First-pass alert triage
- Log summarization
- SQL generation with execution validation
- Runbook assistance
- Incident timeline extraction
Enterprise knowledge work
- Summarizing internal documents
- Editing reports
- Updating spreadsheets
- Producing one-page briefs
- Generating architecture diagrams
- Preparing summary-slide content
RAG applications
- Internal knowledge assistants
- Support copilots
- Policy Q&A
- Documentation search
- Evidence-backed research assistants
AWS specifically highlights workloads such as first response to alerts, agent monitoring, SQL generation, UI/UX testing, fast coding agents, spreadsheet edits, and routine document tasks as strong Sonnet 5.5 candidates.
When Sonnet 5.5 Is Not the Best Choice
Sonnet 5.5 is not automatically the correct Bedrock model for every workload.
Consider Opus 5.5 or heavier human review for:
- Ambiguous strategic decisions
- Large security-sensitive code reviews
- Cross-system architecture with incomplete requirements
- High-impact financial or legal judgment
- Long investigations where the model must determine the plan itself
- Repeated Sonnet failures caused by ambiguity rather than execution difficulty
There is also an important Bedrock-specific limitation: structured outputs are not currently listed as supported for Sonnet 5.5 on bedrock-runtime.
The model can still be prompted to return JSON, but prompt-requested JSON is not the same thing as provider-enforced schema output.
For machine-to-machine workflows:
- Parse the response.
- Validate it against a schema.
- Reject invalid structures.
- Use bounded repair attempts.
- Do not execute destructive tools until validation succeeds.
A Better Production Architecture for Sonnet 5.5
A robust AI system should separate model intelligence from application control logic.
A practical architecture looks like this:
Client
  |
API / Application Layer
  |
Authentication + Authorization
  |
Task Router
  |---- deterministic path
  |---- Sonnet 5.5 default path
  |---- Opus 5.5 escalation path
  |
Amazon Bedrock
  |---- Guardrails
  |---- Knowledge Base / retrieval
  |---- Prompt caching
  |
Tool Layer
  |---- databases
  |---- internal APIs
  |---- search
  |---- code execution
  |
Validation Layer
  |
Observability + Cost Tracking
The critical component is the task router.
A low-risk bug fix with a reproducible test can go directly to Sonnet 5.5. A failed attempt, security-sensitive change, unclear requirement, or high-impact decision can escalate to Opus 5.5.
This creates a quality ladder instead of a one-model bottleneck.
IAM and Security Checklist
AWS's launch example identifies permissions including bedrock:InvokeModel and bedrock:InvokeModelWithResponseStream.
For production workloads, security should go further:
- Grant inference permissions only to application roles that require them.
- Scope policies to approved model resources or inference profiles when practical.
- Review SCP behavior for every cross-Region destination involved.
- Use CloudTrail for auditability.
- Use CloudWatch for error, latency, and utilization monitoring.
- Apply Bedrock Guardrails where policy requires another enforcement layer.
- Separate model permissions from tool permissions.
- Require explicit approval for destructive or irreversible actions.
- Minimize database credentials and infrastructure privileges exposed to agents.
- Log tool calls separately from natural-language responses when auditability matters.
The most dangerous agent failure is often not an incorrect sentence. It is a valid tool call executed with excessive privileges.
Cost Optimization Strategy
A serious Sonnet 5.5 deployment should optimize at several layers.
1. Reduce unnecessary output.
Output tokens are more expensive than input tokens. Clear output contracts such as maximum length, code-only responses, or structured field requirements can reduce spend.
2. Cache stable prefixes.
System instructions, repository rules, tool definitions, schemas, and repeated reference material are strong caching candidates.
3. Tune reasoning effort by task class.
Do not automatically run routine workloads at the maximum reasoning level. Benchmark each task category and choose the lowest effort level that consistently meets the quality threshold.
4. Escalate difficult tasks instead of overthinking every task.
Using Sonnet 5.5 as the default and escalating selected requests to Opus 5.5 can outperform a uniform high-cost strategy.
5. Measure completed-work economics.
A useful metric is:
cost_per_successful_task =
(model_input_cost
 + model_output_cost
 + cache_cost
 + tool_cost
 + retry_cost)
 / accepted_tasks
This captures why Sonnet 5.5 can be cheaper per task even when its headline token prices are not lower than Sonnet 5.
Migration Checklist from Sonnet 5
Sonnet 5.5 is positioned as a natural Sonnet 5 upgrade, but production migration should still be evaluated rather than treated as a model-name replacement.
Use this checklist:
- Replace the previous model or inference-profile ID with the correct Sonnet 5.5 identifier.
- Confirm that each source AWS Region supports the selected Global or Geo profile.
- Test response parsing for thinking blocks followed by text blocks.
- Benchmark latency at multiple effort levels.
- Re-test truncation and maximum-output behavior.
- Re-run prompt-injection evaluations.
- Re-run tool-use safety tests.
- Rebuild golden-set quality benchmarks.
- Measure cost per accepted task rather than token cost alone.
- Test explicit prompt-cache placement.
- Verify JSON/schema validation.
- Confirm Bedrock Guardrail behavior.
- Review SCPs before enabling cross-Region inference.
Anthropic also notes that integrations that previously disabled thinking may require migration changes involving its newer between_tools behavior. Custom reasoning configurations should therefore be checked against current migration guidance before production traffic is switched.
Common Sonnet 5.5 Bedrock Mistakes
Mistake 1: Using the bare model ID with the wrong endpoint.
Model IDs, inference-profile IDs, and endpoints have different routing semantics. Match the identifier to the documented endpoint and deployment mode.
Mistake 2: Assuming Global CRIS is Region-local.
Global cross-Region inference can route processing outside the source Region.
Mistake 3: Reading only the first content block.
Reasoning content can appear before the final text response.
Mistake 4: Comparing only price per million tokens.
Task completion rate and tool-loop efficiency can matter more than the headline token price.
Mistake 5: Filling the 1M context window because it exists.
More context can mean more cost, latency, irrelevant information, and prompt-injection surface.
Mistake 6: Treating requested JSON as guaranteed structured output.
Bedrock currently does not list structured outputs as supported for this model on bedrock-runtime.
Mistake 7: Running every request at Max effort.
Higher reasoning effort is not automatically cost-effective for bounded tasks.
Mistake 8: Ignoring model lifecycle planning.
AWS currently states an EOL no sooner than September 28, 2027, so applications should already have a model-version migration strategy.
Sonnet 5.5 Bedrock FAQ
Is Claude Sonnet 5.5 available on Amazon Bedrock?
Yes. AWS announced Claude Sonnet 5.5 availability on September 28, 2026.
What is the Claude Sonnet 5.5 Bedrock model ID?
The base ID is anthropic.claude-sonnet-5-5. For Global cross-Region bedrock-runtime usage, AWS documents global.anthropic.claude-sonnet-5-5. Current documentation also lists US and EU geographic inference IDs.
What is the Sonnet 5.5 context window on Bedrock?
AWS documents a 1 million-token context window and up to 128K output tokens.
Does Claude Sonnet 5.5 support images?
Yes. AWS lists text and images as supported input modalities, with text output.
Does Sonnet 5.5 support Bedrock Converse?
Yes. Converse, Invoke, and Messages are currently supported through bedrock-runtime.
Does it support OpenAI-style Responses or Chat Completions through Bedrock?
Not currently according to AWS's API compatibility documentation for Sonnet 5.5.
How much does Claude Sonnet 5.5 cost?
Anthropic publishes pricing of $2 per million input tokens and $10 per million output tokens, plus $0.20 per million cache-read tokens and $2.50 per million cache-write tokens. AWS notes that the Bedrock offering is a third-party model billed through AWS Marketplace, so teams should verify the current AWS pricing information when creating production forecasts.
Is Sonnet 5.5 better than Opus 5.5?
Not universally. Sonnet 5.5 is optimized for fast, well-scoped execution, while Opus 5.5 remains better suited to complex and open-ended work requiring sustained judgment.
Is Sonnet 5.5 a good choice for coding agents?
Yes, particularly when tickets and acceptance criteria are clearly defined. Anthropic reports major gains on Terminal-Bench and CursorBench, while AWS specifically highlights feature development, bug fixing, UI testing, SQL generation, and fast coding-agent workloads.
Conclusion
Claude Sonnet 5.5 makes Amazon Bedrock particularly compelling for workloads where throughput, quality, and cost per finished task all matter at once.
Its 1M-token context window, 128K maximum output, adaptive reasoning, improved coding performance, prompt caching, AWS-native integrations, and 30%+ reported generation-speed improvement make it a strong default candidate for scoped coding agents and enterprise knowledge workflows.
The strongest architecture is not necessarily to replace every model with Sonnet 5.5. It is to make Sonnet 5.5 the default execution layer, reserve Opus 5.5 for tasks requiring greater judgment, and use deterministic logic or cheaper models for simple routing and extraction.
Before moving production traffic, benchmark real workloads at multiple effort levels, verify the correct Bedrock inference profile for every Region, cache repeated prefixes, validate machine-readable outputs, and measure cost per accepted result. That is where the practical advantage of Sonnet 5.5 on Amazon Bedrock is most likely to become visible.
Continue Reading
More articles connected to the same themes, protocols, and tools.
Referenced Tools
Browse entries that are adjacent to the topics covered in this article.