On This Page8 sections
Key Takeaways
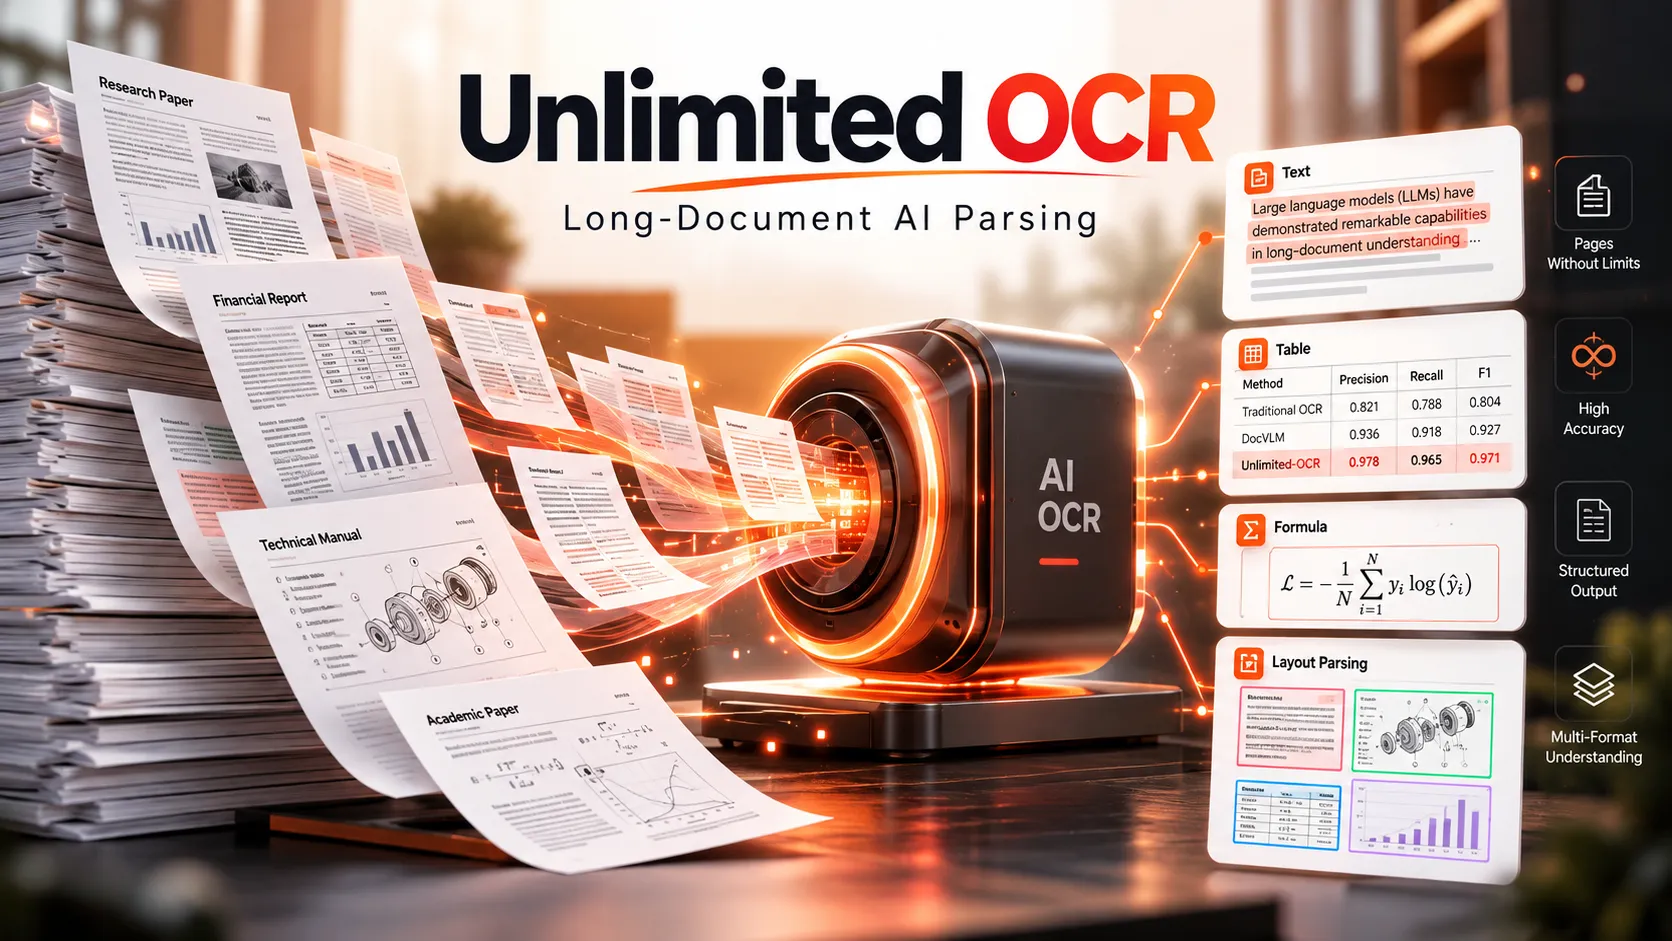
- Unlimited-OCR is Baidu's open-source vision-language OCR model, released on June 22, 2026, for extracting text, formulas, tables, and reading order from document images and multi-page scans.
- Its main innovation, Reference Sliding Window Attention (R-SWA), keeps every input/reference token accessible while retaining only a bounded window of generated tokens. This prevents the output-side KV cache from growing with every generated token.
- In Baidu's technical report, Unlimited-OCR scored 93.23 on OmniDocBench v1.5 versus 87.01 for the original DeepSeek-OCR, and 93.92 on v1.6. These are authors' reported results, not an independent reproduction.
- The model uses a roughly 3B-parameter mixture-of-experts architecture with about 0.5B active parameters, a DeepEncoder vision stack, and a 32,768-token configured length.
- Unlimited does not mean infinite. Input-page count, image detail, decoding limits, GPU memory, and recognition errors still matter.
What Is Unlimited-OCR?
Unlimited-OCR, formally introduced in the paper Unlimited OCR Works: Welcome the Era of One-shot Long-horizon Parsing, is a document-understanding model developed by Baidu. Unlike a simple screenshot-to-text website, it is a downloadable model intended for developers building document parsing, archival search, research ingestion, and automated extraction systems.
The official GitHub repository provides inference examples and an MIT license; Hugging Face hosts its model weights, and an official demo Space offers a convenient way to explore the project.
Its defining use case is one-shot, multi-page OCR: instead of recognizing every PDF page in isolation and stitching the results together afterward, the model can receive multiple document-page images as a shared visual reference and generate a continuous parsing result. Here, one-shot refers to one continuous generation task, not literally a single decoder computation for every output token.
Why Conventional OCR Struggles With Long Documents
Traditional OCR stacks generally detect regions, recognize the text in each region, and reconstruct document order. Modern end-to-end vision-language models can combine many of those steps, but autoregressive decoding introduces another bottleneck: the key-value (KV) cache.
With standard causal attention, each generated token adds cached representations. A decoder that must produce a long book transcription spends progressively more memory retaining historical output and more work attending to it. That can reduce throughput and force pipelines to break documents into page-sized jobs.
Page-by-page OCR remains useful, particularly when pages are independent. However, it can complicate processing of multi-page reading order, page-boundary context, repeated headers, and continued tables. Unlimited-OCR specifically targets the long-output memory problem rather than claiming that all page segmentation is obsolete.
How Unlimited-OCR Works: DeepEncoder and R-SWA
1. A compressed visual reference
Unlimited-OCR inherits the DeepEncoder design from DeepSeek-OCR. The paper describes a SAM-ViT/CLIP-ViT-derived vision stack that can compress a 1024 × 1024 page image into approximately 256 visual tokens. This matters because every token representing the input document remains available during output generation.
The model retains two image-processing configurations:
- Base: 1024 × 1024 images, used for multi-page parsing.
- Gundam: Dynamic, crop-based processing for a single image; the repository's sample uses
base_size=1024,image_size=640, andcrop_mode=True.
2. Reference Sliding Window Attention
R-SWA separates attention into two parts:
- Reference tokens: The compressed document images and prompt, accessible to each generated token.
- Recent output tokens: A fixed-size causal sliding window of prior generated text; the paper's default attention window is 128 tokens.
A useful approximation of the number of cached token positions is:
Standard attention:  reference_tokens + generated_tokens
R-SWA:               reference_tokens + min(window_size, generated_tokens)
For a fixed input, R-SWA's cache stops growing once the output window is full. This is bounded output-history memory, not constant memory for arbitrarily many document pages: adding pages still increases the reference prefix.
The distinction also explains why ordinary sliding-window attention is not equivalent. R-SWA deliberately keeps original visual tokens outside the rolling state, so the model can repeatedly consult the unchanged document rather than relying on an increasingly lossy summary of it.
3. A sparse decoder
The paper describes a 3B-total / 0.5B-active mixture-of-experts (MoE) decoder inherited from DeepSeek-OCR's design. Active parameters describe the approximate computation used for a token, not the number of model weights that must be stored. GPU planning must account for weights, vision processing, KV cache, image inputs, and runtime overhead.
The researchers continued training from the DeepSeek-OCR checkpoint using about 2 million document samples, including synthesized multi-page examples spanning 2–50 pages. Their reported training setup packed samples into 32K-token sequences; this was an engineering-scale training effort, not a lightweight fine-tune performed on a laptop.
Unlimited-OCR Benchmarks: Accuracy and Speed
OmniDocBench results
The published evaluation reports the following overall scores. Versions v1.5 and v1.6 use different evaluation sets, so figures should only be compared within the same version.
| Model | OmniDocBench v1.5 | OmniDocBench v1.6 |
|---|---|---|
| DeepSeek-OCR | 87.01 | Not reported in this comparison |
| DeepSeek-OCR 2 | 89.17 | 90.25 |
| dots.ocr | 88.41 | 90.77 |
| Qianfan-OCR | Not reported here | 93.90 |
| Unlimited-OCR | 93.23 | 93.92 |
On v1.5, Unlimited-OCR improved 6.22 points over DeepSeek-OCR. Its formula CDM score was 92.61, table TEDS 90.93, and text edit distance 0.038 (lower is better). On v1.6, its overall 93.92 was only 0.02 points above Qianfan-OCR's 93.90—a reminder that a marginal leaderboard lead is not proof of a universal advantage.
These are research-paper results under the authors' evaluation conditions. The paper also draws comparison figures for other models from the OmniDocBench repository, so it should not be interpreted as an independently standardized production test of every system.
What happens with 40-plus pages?
In the authors' in-house long-document evaluation, text edit distance increased from 0.0362 for two-page documents to 0.1069 for documents with 40-plus pages. Their 35-gram distinctness score at 40-plus pages was 96.90%. The report attributes many long-document errors to small text being difficult to read in the 1024-pixel Base setting.
Practical implication: A successful continuous run does not guarantee perfect text. Output length, page density, font size, and review requirements must inform the size of each document batch.
Does R-SWA actually improve throughput?
Under the paper's OmniDocBench setup with 512 concurrent sequences, Unlimited-OCR generated 5,580 tokens/second versus 4,951 tokens/second for DeepSeek-OCR—about 12.7% more throughput.
In a separate theoretical throughput-ceiling experiment with a short fixed prefix, the models produced approximately 7,848 versus 5,823 tokens/second at 6,144 output tokens, respectively, favoring Unlimited-OCR by about 35%. Neither figure is a promise about single-user latency, consumer GPUs, or full PDF processing time; rendering, prefill, upload, and post-processing also contribute to end-to-end latency.
Unlimited-OCR vs. DeepSeek-OCR and Other Alternatives
| System | Main approach | Best reason to consider it | Important trade-off |
|---|---|---|---|
| Unlimited-OCR | Compressed visual encoder + MoE decoder + R-SWA | Long continuous document transcription with bounded output KV cache | Finite 32K configuration; multi-page image detail can be limiting |
| DeepSeek-OCR | Compressed visual encoder + conventional decoder attention | Established baseline and compatible OCR-oriented workflow | Output-history KV cache grows with generation |
| DeepSeek-OCR 2 | Updated DeepSeek OCR architecture | Strong alternative for document recognition | Compare on the same benchmark and deployment conditions |
| PaddleOCR / PaddleOCR-VL | OCR pipelines and compact document-understanding models | Modular extraction, multilingual workflows, deployment flexibility | Quality and speed depend on which pipeline/model is chosen |
| Tesseract | Traditional recognition engine | Lightweight, offline printed-text OCR without LLM serving | Complex layouts, formulas, and semantic structure often need extra processing |
Unlimited-OCR is especially interesting when long-output decoding is the bottleneck. For clean, single-page documents or tightly constrained CPU environments, a simpler recognizer can still deliver a better cost-performance balance. For receipts and invoices requiring reliable fields, an extraction/validation layer remains essential regardless of the underlying OCR model.
How to Run Unlimited-OCR Locally
Option 1: Hugging Face Transformers
The official instructions were tested with Python 3.12.3, CUDA 12.9, PyTorch 2.10.0, and Transformers 4.57.1 on NVIDIA GPUs. Install versions compatible with the target CUDA driver and follow the repository for its complete dependency list.
pip install torch==2.10.0 torchvision==0.25.0 transformers==4.57.1 pillow==12.1.1 einops==0.8.2 addict==2.4.0 easydict==1.13 pymupdf==1.27.2.2 psutil==7.2.2 matplotlib==3.10.8Minimal single-image example based on the project's published inference interface:
import torch
from transformers import AutoModel, AutoTokenizer

model_id = 'baidu/Unlimited-OCR'
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModel.from_pretrained(
    model_id,
    trust_remote_code=True,
    use_safetensors=True,
    torch_dtype=torch.bfloat16,
).eval().cuda()

model.infer(
    tokenizer,
    prompt='<image>document parsing.',
    image_file='page.png',
    output_path='./ocr-output',
    base_size=1024,
    image_size=640,
    crop_mode=True,
    max_length=32768,
    no_repeat_ngram_size=35,
    ngram_window=128,
    save_results=True,
)
Replace page.png with a real image. This is model-code execution, not a browser-only OCR conversion: trust_remote_code=True permits code from the model repository to execute locally. Review and pin trusted revisions in controlled environments.
Option 2: Multi-page images and PDFs
The model's infer_multi method accepts an ordered list of page images. PDFs must first be rendered into images; the official example uses PyMuPDF at 300 DPI and then invokes multi-page parsing with image_size=1024, max_length=32768, and ngram_window=1024.
The multi-page setup uses Base mode, not the single-image Gundam cropping configuration. Note that ngram_window configures repetition prevention; it should not be confused with the R-SWA attention-window size described in the paper.
For very large PDFs, benchmark several page-group sizes rather than passing every page in one job. More pages increase the visual prefix, and generated text still needs to fit the configured length.
Option 3: vLLM or SGLang serving
For concurrent workloads, the project also documents vLLM and SGLang inference. The official vLLM deployment recipe provides a dedicated container, with the following pattern:
docker run --rm --gpus all --network host --ipc host vllm/vllm-openai:unlimited-ocr baidu/Unlimited-OCR --trust-remote-code --logits_processors vllm.model_executor.models.unlimited_ocr:NGramPerReqLogitsProcessor --no-enable-prefix-caching --mm-processor-cache-gb 0Do not omit the model-specific decoding recipe. The vLLM guide requires a literal <image> prompt prefix, skip_special_tokens=False, a no-repeat-ngram logits processor, and appropriate window parameters (typically 128 for one image or 1024 for multi-page inputs). Missing these settings can produce empty output or repeated structural tokens.
The same recipe lists 8 GB VRAM as a minimum for basic BF16 inference on one GPU; long multi-page inputs, concurrency, and production headroom can require substantially more. That minimum should not be treated as a 40-page performance guarantee.
Practical Use Cases and Production Design
Research papers and technical documents
Extract paragraphs, equations, table content, and reading order from scanned papers. Preserve the original page image and page identifier alongside recognized text so citations can be verified. Mathematical expressions and footnotes warrant manual or rule-based spot checks.
Archives and book digitization
Continuous generation can reduce page-boundary fragmentation. For a large archive, use document-specific batching, store page-level provenance, and flag suspiciously short or repetitive outputs. Do not rely on one uninterrupted generation for an entire collection.
Retrieval-augmented generation (RAG)
An OCR-to-RAG pipeline should include these steps:
- Classify pages: Reuse embedded PDF text where it is already accurate; send image-only or poor-quality pages to OCR.
- Preprocess: Correct rotation, cropping, contrast, and low-resolution inputs before recognition.
- Parse and normalize: Keep headings, tables, and page boundaries where the output supports them.
- Validate: Check document identifiers, numeric fields, unexpected omissions, and missing pages.
- Chunk and index: Store text with source-page metadata, then evaluate retrieval quality separately from OCR accuracy.
This workflow avoids paying the GPU cost of OCR on already-selectable text and makes answers easier to trace back to source documents.
Invoices and compliance-sensitive records
OCR can recover candidate fields but should not be the sole system of record. Cross-check totals, currencies, dates, and tax calculations; capture confidence and review decisions in a separate application layer. For sensitive documents, assess data retention and access controls before using any hosted demonstration.
Limitations, Common Errors, and Troubleshooting
- The name is aspirational. The authors explicitly state that finite context and an expanding reference prefix prevent truly unlimited parsing; longer-context models and reference-cache retrieval are future research directions, not features to assume are available.
- Small fonts can fail. Multi-page Base mode uses 1024 × 1024 page representation. Splitting dense documents or selecting an appropriate image-processing workflow may improve legibility.
- Output can be incomplete. A 32K token budget is not an infinite output allowance. Detect truncation, missing final pages, and unexpected termination.
- Repeated tokens can appear. Ensure the required anti-repetition processor and settings are enabled in the selected inference engine.
- Structured output needs cleanup. Raw results may contain
<|ref|>and<|det|>tokens or bounding-box annotations. Use the documented post-processing strategy instead of assuming the raw response is publication-ready Markdown. - Accuracy is document-dependent. Test handwriting, mixed scripts, rotated pages, stamps, chemical notation, and complex tables on representative files before deployment.
- Open source is not zero-cost hosting. The project uses an MIT license, but GPUs, queues, storage, security controls, and quality review still cost money.
For reliable evaluation, create a held-out sample set and track character error rate, table structure fidelity, formula correctness, reading-order accuracy, pages per minute, and cost per accepted page. These operational measurements are often more useful than a single leaderboard score.
Frequently Asked Questions
Is Unlimited-OCR really unlimited?
No. It bounds output-side attention memory, but the published setup still uses a 32K-token maximum configuration, and input visual tokens scale with the number of pages. The paper demonstrated 40-plus-page cases rather than arbitrary-length perfect transcription.
Is Unlimited-OCR free and open source?
The official code and model are publicly available under MIT terms. Self-hosting involves computing and operating costs, while third-party online tools may follow unrelated pricing and privacy policies.
Is Unlimited-OCR a website or an API?
Primarily, it is an open model and repository, not a guaranteed free public API. It can be hosted behind an API using supported inference frameworks. Unrelated sites with similar 'Unlimited OCR' names should not be mistaken for the official Baidu model.
Does it support PDF files directly?
The published local workflow renders PDF pages into images first, then supplies those images to the model. Searchable-PDF creation, field-level JSON, and spreadsheet exports are separate application functions rather than guaranteed native model outputs.
Is it better than DeepSeek-OCR?
On the authors' reported OmniDocBench v1.5 results, yes: 93.23 versus 87.01, alongside a favorable long-output memory profile. Whether it is better for a specific language, GPU, scan type, or latency target requires a matched test.
Conclusion
Unlimited-OCR's contribution is architectural: it keeps a stable visual reference while bounding attention to recent generated output, making continuous multi-page parsing more feasible without indefinitely growing the decoder's KV cache. Its reported benchmark improvements are promising, but image resolution, output limits, and real-world document quality still define the practical ceiling.
To evaluate it, start with the official model weights, follow the GitHub inference guide, and compare a representative set of documents against DeepSeek-OCR and a simpler OCR pipeline. Choose the system that produces the most verified pages per dollar—not merely the highest headline score.
Continue Reading
More articles connected to the same themes, protocols, and tools.
VisionHOPE GPU Requirements (2026): VRAM, CUDA Support, and Hardware for Inference and Training
Google Search Console Generative AI Features (Beta): How to Track AI Overviews and AI Mode Visibility in 2026
Hostinger AI Builder Explained: The New AI Platform for Building Websites, Apps, and SaaS in 2026
Referenced Tools
Browse entries that are adjacent to the topics covered in this article.